
What Counts as Starting, and What Counts as Coming Back in Cohort Retention
Updated October 2026
To see whether people come back, group them by when they started and count each group at its own age. Cohort retention shows what share of each group came back at each age. Looking only at overall totals can hide differences between groups [1], and splitting by cohort brings them out. Two choices make the answer honest: what counts as starting, and what counts as coming back [2] [3]. Change either one and the number changes, so say both before you read a single figure. This page defines both, shows how to read the table, and lists the traps.
What a cohort and a start event are
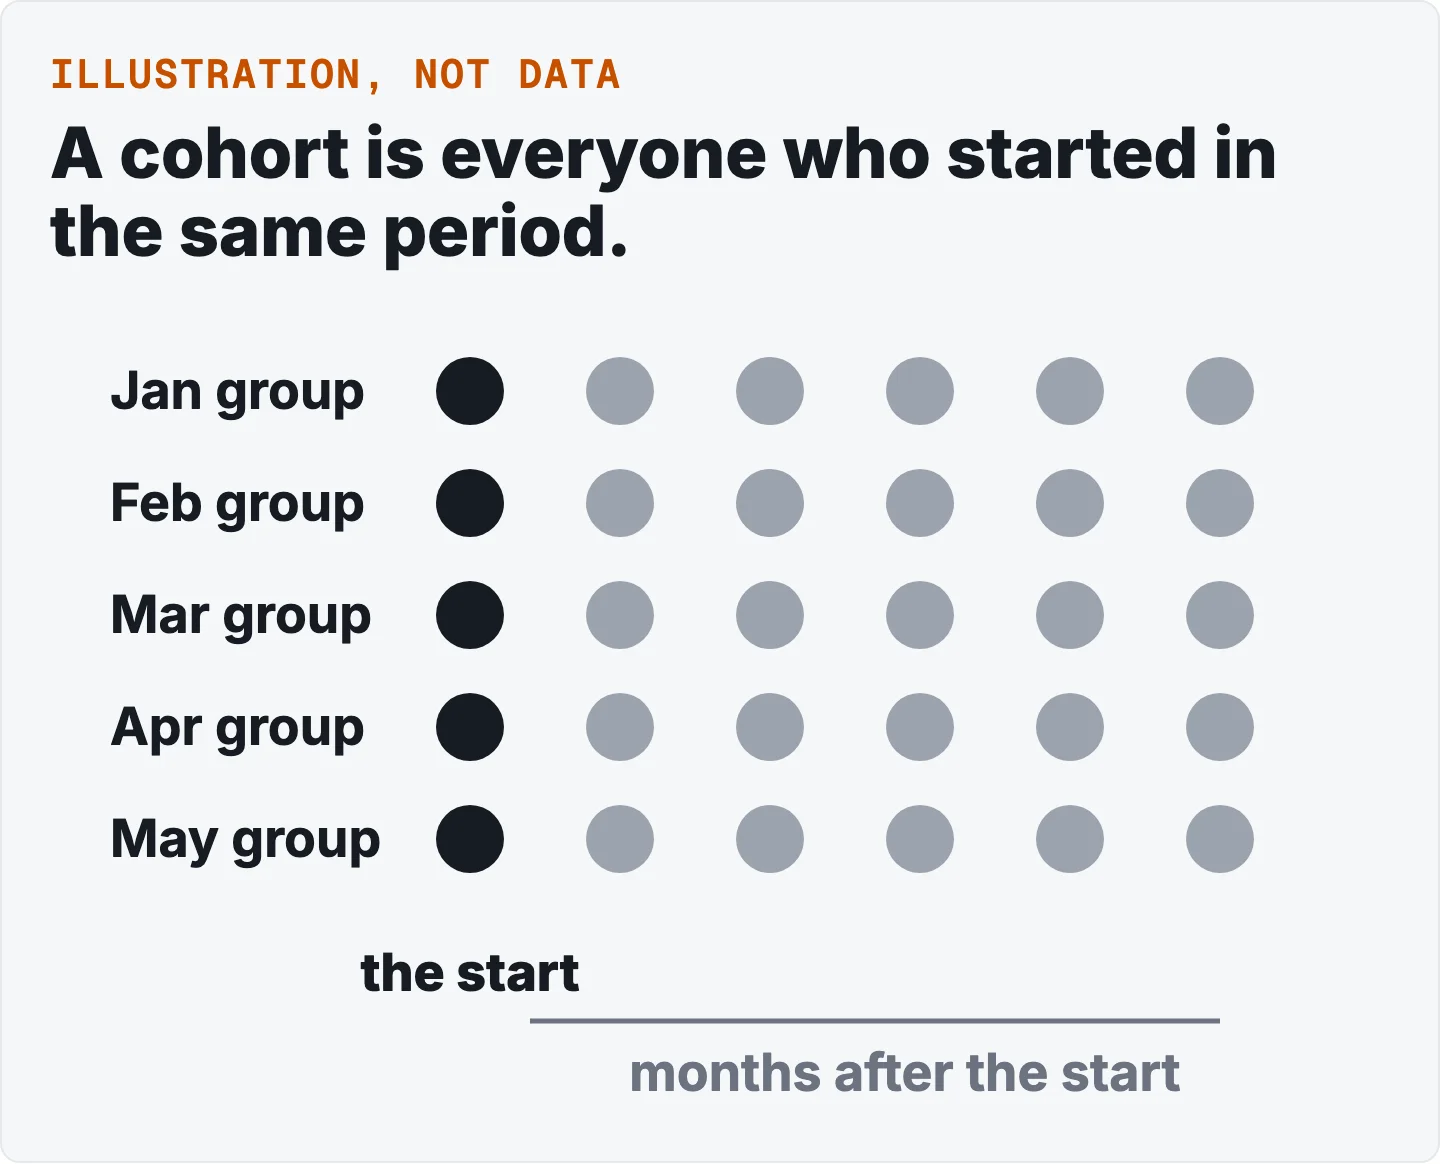
A cohort is a group whose members share a characteristic or an experience within a defined span of time [1]. In retention work the shared thing is the start. Analytics products define a start event as the event that qualifies someone for the analysis, and a cohort as the people who did the start event on the same date or in the same period [2]. Examples of ours: for a store, the start is usually a first purchase; for an app, it might be a first sign-in.
Three rules follow from how these products define it.
- Each person joins once. A person must do the start event once to join a cohort, and a duplicate can be excluded so that each person counts only in the period of their first start event [2] [3].
- The cohort size is the denominator. The number of people who did the start event in each cohort is fixed, and every later period is a share of that fixed number [3].
- Periods are elapsed time. Age is counted from each person's start, not from the calendar date. In one product's definition, a one-day period needs a full 24 hours to elapse [2]. That is why each cohort is read at its own age: month one after starting, month two, and so on.
Splitting by cohort matters because totals alone can hide differences between groups [1]. Our illustration, not a sourced finding: a line of new customers can look like growth while the ones who came before quietly stop returning.
Two meanings of "came back"
The second choice is the return event: the thing a person must do again to count as retained. In analytics products it is one or more events that a user must engage with to count as returning [2]. It has to match your question. A visit, a purchase and a reorder are three different return events, and they give three different tables.
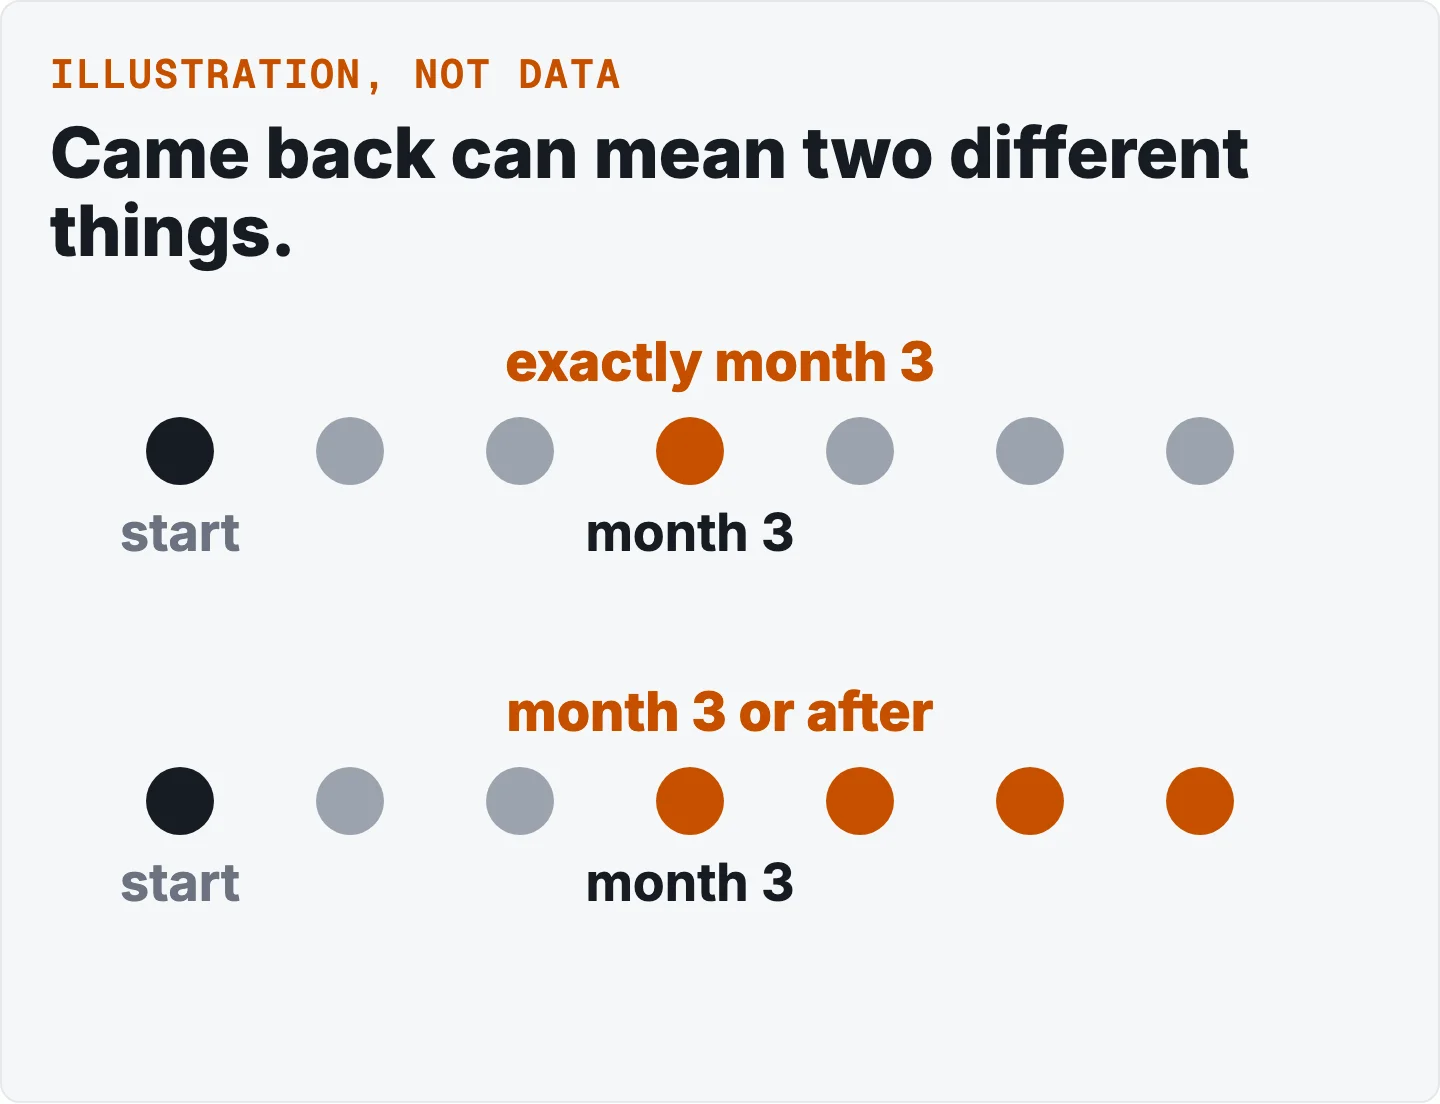
Then comes the timing. Two definitions are in common use [2] [3].
| Name | Counts a person as retained when |
|---|---|
| Exactly in period N (bounded, also called N-day) | they return in exactly the stated period |
| In period N or any later one (unbounded, also called rolling) | they return in that period or any later one, at least once, counted once |
Read the second one carefully. Counting "in period N or any later one" can only fall as N grows. Someone whose only return is in period four counts at period three, but not at period five. Counting "exactly in period N" has no such rule and can move up and down from one period to the next.
A product's remark that the unbounded measure can rise as the measurement period grows is a different thing [3]. It describes more data arriving for the same cohort, not a larger N. A third definition, "by period N", is cumulative and only rises. These readings of the two definitions are ours.
The practical rule is short: numbers are comparable only inside one stated definition. The same word, "retained", covers both senses across products, and comparing the unbounded column across cohorts with different amounts of follow-up may be unreliable [3].
The free cohort retention tool uses a single-age definition: a customer counts at age N if they bought in the Nth period after the period of their first purchase, one age at a time. The period is a month by default. It measures observed return in purchase data. A returning purchase is not a contract renewal, and this page says "came back", not "renewed", for that reason. The sources behind this page describe contractual and event-based products.
Reading the table
A retention table has one row per cohort and one column per age. Rows follow one cohort over its life. Columns compare cohorts at the same age. Darker shading means higher retention [3].
Read it in two directions. Down a column, ask whether newer groups are doing better or worse than older ones at the same age. Along a row, ask how one group fades.
One practitioner rule of thumb, from a single vendor blog and not a tested result: a curve that levels off above zero suggests a stable core of people, and one that keeps falling toward zero does not [4]. Treat it as a prompt to look, not as a finding.
Retention and churn are two sides of one question. In one vendor's convention, one minus the unbounded retention rate equals the churn rate [3]. Churn itself can also cover customers who keep receiving service at a reduced level [5], so check which meaning a number uses. For churn on its own, there is a free churn tool.
Why a line can rise
Retention rates sometimes rise over time, and the first instinct is that people grew more loyal. Fader and Hardie show a case where that instinct is wrong. In their subscription model, the retention rate is an increasing function of time even though each individual's chance of staying is constant [6]. The rise is due to heterogeneity: the customers with high churn leave early, and the ones who remain have lower churn probabilities [6].
They call this the "ruse of heterogeneity" [6]. In one sentence: the customers with high churn leave early, so those who remain have lower churn probabilities, and nobody changed their mind [6]. A crowd leaving a party is our analogy for it: the ones who were never going to stay go first. An aggregate rise does not prove that individuals changed [6].
Their shifted-beta-geometric model projects retention for subscriptions, with constant individual churn and a spread of churn across customers. It is built for contractual data. It is not what the free tool computes [6].
Traps
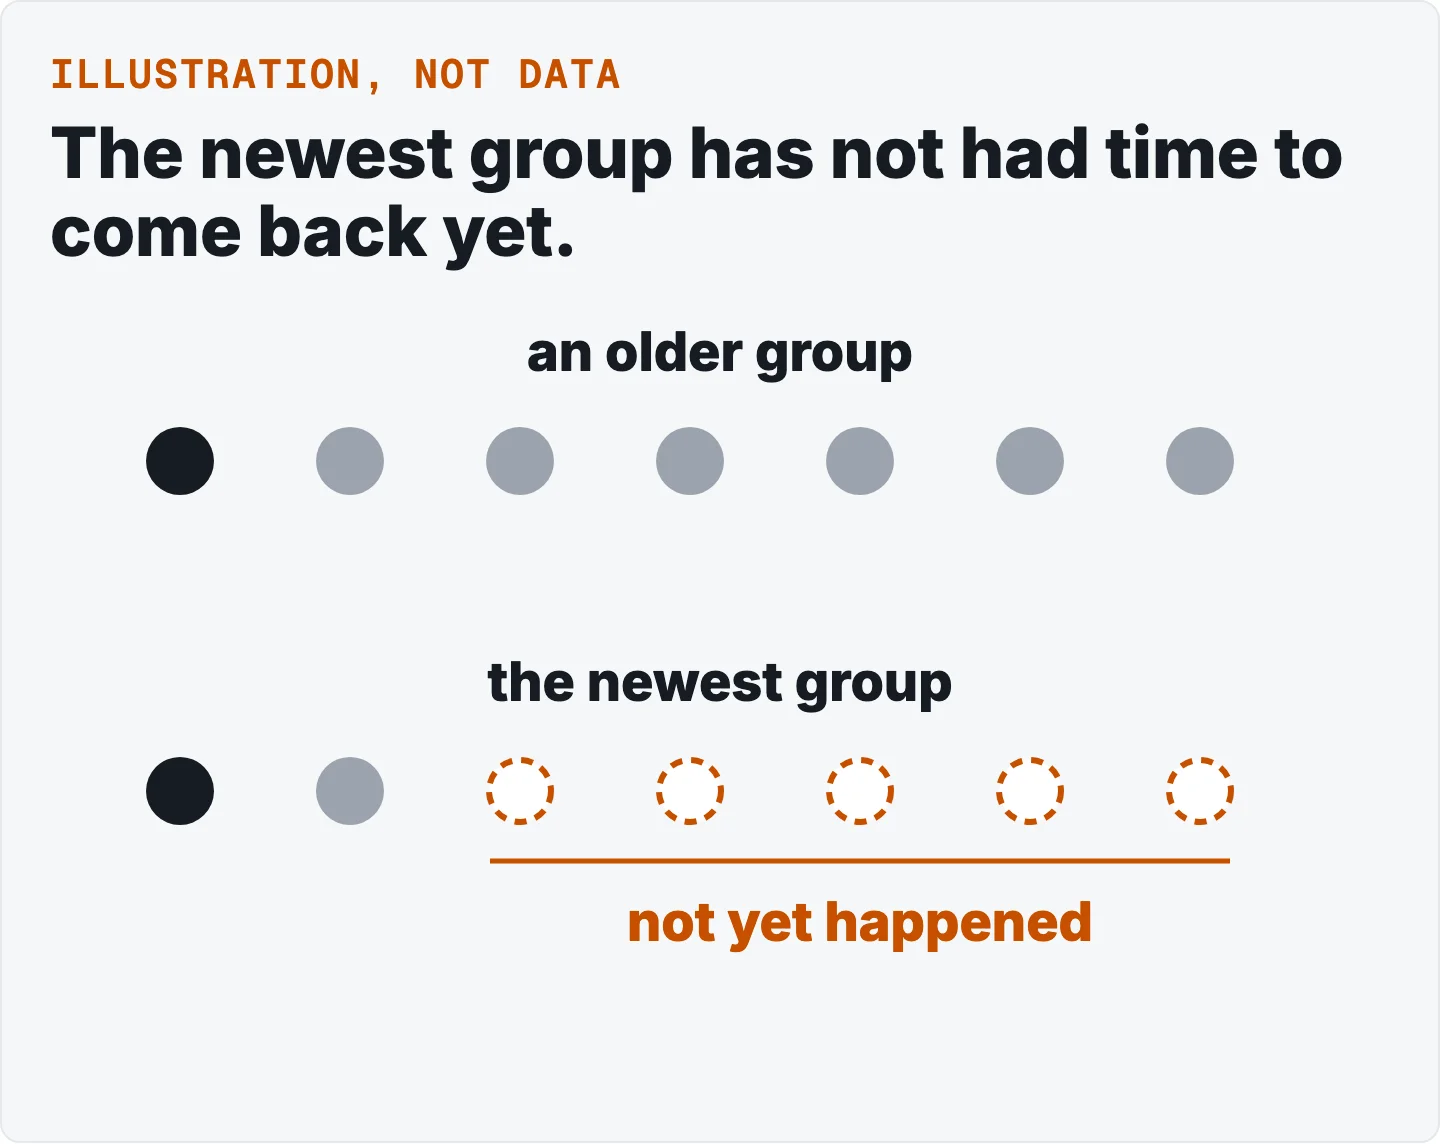
A period still in progress is not a period that is over. A customer who started last month has not had the chance to come back in month six. In statistics this is right censoring: a data point is known to be above some value, but not by how much [7]. The Kaplan-Meier estimator handles it by keeping each person in the at-risk count only up to the point they leave observation [8]. For time-to-event data, there is a free survival analysis tool. Our working rule for a table is simpler: leave the unfinished cells empty, and never count them as people who left.
| Cohort | Month 1 | Month 2 | Month 3 |
|---|---|---|---|
| A (oldest) | observed | observed | observed |
| B | observed | observed | not yet happened |
| C (newest) | observed | not yet happened | not yet happened |
Illustration, not data.
Counting only who is still here. Survivorship bias is the error of concentrating on the entities that passed a selection process and ignoring those that did not [9]. That source does not discuss retention. The application is ours: a retention figure computed only from accounts that are still active leaves out exactly the people whose leaving the figure was meant to show.
Pooling cohorts. In Simpson's paradox, a trend that appears in several groups can disappear or reverse when the groups are combined; it needs very different group sizes and a confounder with a large effect [10]. That source does not discuss retention either. The parallel is ours: one pooled rate across cohorts of different size and mix can say something none of the cohorts says.
A loose return event. Metrics that are not tied to an action, such as page hits or downloads, are called vanity metrics [1]. Our reading: a return event that anyone can trigger without meaning to will flatter the curve.
Retention is not always the goal. Not all long-term customers are profitable or worth retaining, and the link between retention and outcomes can be non-linear and vary by segment and industry [11]. Churn can also be kept artificially low by making it hard to cancel [5], and some firms deliberately shed unprofitable customers [5].
A short window. The observed time horizon is often quite limited, which is a major problem if you want to project lifetime value from the observed curve [6].
Questions people ask
These questions are inferred from the sources, not taken from observed search queries.
What is cohort retention?
The share of a group that started together who come back, period by period. The start event and the return event define the group and the count [2].
How is it different from churn?
In one vendor's convention, churn is one minus the unbounded retention rate [3]. Churn can also cover customers who stay but at a reduced level, so confirm which meaning is in use [5].
What is the difference between N-day and unbounded retention?
N-day (bounded) counts a person only if they return in exactly the stated period. Unbounded counts a person if they return in that period or any later one [2] [3].
Why does my retention go up in later periods?
Two reasons are described. Early leavers drop out, so those who remain have a lower chance of leaving [6]. And in the unbounded measure, more of the data arrives as the window lengthens, which is our reading of one product's remark [3].
Why not just average all customers?
Cohorts differ, and recent ones are unfinished. Totals can hide differences between groups [1], and an unfinished period is incomplete follow-up, not a loss [7].
How do I handle customers who joined recently?
Count each one only for the periods you could observe. The Kaplan-Meier idea is to keep a person in the at-risk count up to the point they leave observation [8].
What counts as "came back"?
Whatever return event you define. It must match the question you are asking [2].
Is higher retention always better?
Not necessarily. Long-term customers are not always profitable [11].
Can I forecast retention?
For subscriptions, a probability model exists that combines constant individual churn with a spread across customers [6]. It applies to contractual data. The free tool measures observed return and does not make that forecast.
See it done with numbers
Run the free cohort retention tool on your own purchase file.
References
- Wikipedia. Cohort analysis. Page
- Adobe. Analytics, retention rates. Read October 2026. Page
- Hackle. Retention analysis. Read October 2026. Page
- MetricGate. Retention curves in product analytics. Read as a summary of the page, cited once as a practitioner rule of thumb. Page
- Wikipedia. Customer attrition. Page
- Fader, P. S. and Hardie, B. G. S. (2007). How to Project Customer Retention. Journal of Interactive Marketing 21(1), 76-90. Abstract · Paper (PDF)
- Wikipedia. Censoring (statistics). Page)
- Wikipedia. Kaplan-Meier estimator. Page
- Wikipedia. Survivorship bias. Page
- Wikipedia. Simpson's paradox. Page
- Wikipedia. Customer retention. Page